Preferences
Privacy is important to us, so you have the option of disabling certain types of storage that may not be necessary for the basic functioning of the website. Blocking categories may impact your experience on the website. More information
Privacy is important to us, so you have the option of disabling certain types of storage that may not be necessary for the basic functioning of the website. Blocking categories may impact your experience on the website. More information
Robots.txt for AI crawlers: the user agents of OpenAI, Anthropic, Perplexity and Google, what each one does, and a configuration that keeps you citable.
Summarize this article with AI
Your robots.txt for AI crawlers has become a business decision, not just a technical file. The same file that once only talked to Googlebot now decides whether ChatGPT, Claude, Perplexity and Gemini can read, quote and link your pages. The format itself has not changed: it is still the Robots Exclusion Protocol standardised as RFC 9309, with user agents, Allow and Disallow lines. What changed is the number of agents, and the fact that one vendor can run several bots with different purposes.
Most AI vendors now separate training, search indexing and user-triggered fetching into different user agents. The table summarises the main ones as documented by each vendor.
| Vendor | User agent | Purpose | Effect of blocking |
|---|---|---|---|
| OpenAI | GPTBot | Training data for OpenAI models | Content not used for future training |
| OpenAI | OAI-SearchBot | Indexing for ChatGPT search | Pages may not appear as cited results in ChatGPT search |
| OpenAI | ChatGPT-User | Pages fetched when a user asks ChatGPT to visit them | ChatGPT cannot open your page on request |
| Anthropic | ClaudeBot | Training data for Claude models | Content not used for future training |
| Anthropic | Claude-SearchBot, Claude-User | Search quality and user-requested fetches | Less visibility in Claude answers that search the web |
| Perplexity | PerplexityBot, Perplexity-User | Search index and user-requested fetches | Less likely to be cited in Perplexity |
| Googlebot | Google Search, including AI Overviews and AI Mode | Removal from Search entirely | |
| Google-Extended (token) | Use of content for Gemini models and grounding outside Search | No effect on Search ranking | |
| Apple | Applebot-Extended (token) | Use of content for Apple's generative models | Applebot can still crawl for Siri and Spotlight |
| Common Crawl | CCBot | Open web archive reused by many AI datasets | Content absent from future crawls of the archive |
Sources: OpenAI crawler documentation and Google's list of common crawlers. Names change occasionally, so check each vendor's page before editing the file. Our glossary entries on AI crawlers and OpenAI crawlers keep the definitions short.
For most businesses that want customers, no: block training if you must, keep search crawlers open. The trade-off depends on what you sell:
Explicit groups per user agent, with search bots allowed and a clear choice for training bots. Example for a business that wants AI visibility but prefers not to feed training data:
User-agent: OAI-SearchBot
User-agent: ChatGPT-User
User-agent: Claude-SearchBot
User-agent: Claude-User
User-agent: PerplexityBot
User-agent: Perplexity-User
Allow: /

User-agent: GPTBot
User-agent: ClaudeBot
User-agent: Google-Extended
User-agent: Applebot-Extended
User-agent: CCBot
Disallow: /

User-agent: *
Disallow: /admin/
Sitemap: https://www.example.com/sitemap.xml
Remove the second group if you are happy for your content to be used in training. Our free robots.txt generator builds the file, and the robots.txt checker shows which agents a live file actually allows.
The most common one is a blanket rule copied from a forum. Frequent errors:
No, it only opens the door. Once crawlers can read your pages, citation depends on whether those pages answer questions clearly, are structured for extraction and are confirmed by other sources. Clean structured data for AI search, answer-first sections and an optional llms.txt file help the next step.
Treat AI crawlers as separate decisions: open the search and user-fetch bots, choose deliberately for training bots, and verify that your server applies the same policy. Then measure whether the open door turns into citations. Sorank tracks your brand in ChatGPT, Claude and Gemini every week and publishes content structured to be cited: start with a 3-day free trial.

Not by itself. GPTBot collects data for training OpenAI models. ChatGPT search relies on a different crawler, OAI-SearchBot, and on ChatGPT-User for pages a user asks it to open. Blocking only GPTBot limits training use while leaving your pages eligible to appear and be linked in ChatGPT search.
No. Google-Extended is a robots.txt token, not a separate crawler, and Google states that it does not affect inclusion or ranking in Google Search. AI Overviews and AI Mode are part of Search and use Googlebot. Google-Extended controls whether your content is used for Gemini models and grounding outside Search.
The major vendors document their user agents and state that their crawlers follow robots.txt, with nuances for fetches triggered directly by a user. Some less transparent bots have been reported to ignore it. For strict enforcement, combine robots.txt with server or firewall rules based on user agent and published IP ranges.
 AI Meta Description GeneratorAI Blog Title Generator
 Google Indexability CheckerAI Blog Outline Generator
 UTM Link Builder
 Keyword Clustering ToolCanonical Tag Checker
 XML Sitemap GeneratorBroken Link CheckerAI SEO Title GeneratorHeadline AnalyzerSERP Preview ToolRedirect Checker
 Hreflang Tag GeneratorHeading Structure AnalyzerHTTP Headers CheckerFavicon Extractor
 SERP CTR Calculator
 SEO vs Paid Search Savings Calculator
 SEO Share of Voice Calculator
 SEO ROI Calculator
 SEO Traffic and Revenue Forecast Calculator
 SEO Budget Calculator
 SEO Break-Even Calculator
 SaaS SEO ROI Calculator
 ROAS Calculator
 Reading Time Calculator
 Ranking Gain Simulator
 Organic Traffic Value Calculator
 Organic Traffic Estimator
 LTV to CAC Ratio Calculator
 Local SEO ROI Calculator
 Link Building Cost Calculator
 Keyword Value Calculator
 Keyword Opportunity Score Calculator
 Keyword Density Calculator
 GEO ROI Calculator
 GEO Content Investment Calculator
 Ecommerce SEO ROI Calculator
 Customer Lifetime Value Calculator
 Customer Acquisition Cost Calculator
 CTR Calculator
 Cost Per Article Calculator
 Conversion Rate Calculator
 Content Marketing ROI Calculator
 ChatGPT Referral Traffic Estimator
 Bounce Rate Calculator
 Backlink ROI Calculator
 AI Visibility Score Calculator
 AI Traffic Value Calculator
 AI Share of Voice Calculator
 Cost of AI Invisibility Calculator
 AI Citation Rate Calculatorllms.txt ValidatorAI Overview CheckerRobots.txt Checker
 AI SEO AuditLLM Readability CheckerSearchGPT Readiness Checker
 Structured Data LLM AuditWebsite Crawlability AI AuditWhy ChatGPT Is Not Recommending My Website
 Gemini Ranking ToolPerplexity Ranking CheckerLLM Citation CheckerAnswer Engine Optimization AuditGEO AuditAI Search Visibility TestChatGPT Visibility Checkerllms.txt Generator
 URL ExtractorWebpage to MarkdownSitemap CheckerSERP Volatility SensorPage Size Checker
 Word Counter
 Slug GeneratorSchema GeneratorRobots Generator
 OG PreviewMeta Tags Generator
 Image CompressorFavicon Generator
 On-Page SEO Audit
 Backlink Analysis Tool
 Keyword Research Tool
 Domain Authority Checker
THEY TRIED SORANK BEFORE YOU
 “I tested Sorank on a real client site and it's insane. It does everything an agency would bill you $1500 a month for. It's going into production on that client now.”
 Guillaume Guersanguersanguillaume.com“We are an Ads agency and we wanted to get our SEO back on track once and for all. Sorank gave us a clear view of our site, helped us prioritize optimizations, and properly structure our content. The tool is easy to use, well designed for a team, and very practical for centralizing tracking without having to juggle multiple platforms. A very solid foundation to start fresh with our SEO.”
 Gaspard MadouiAds Agency
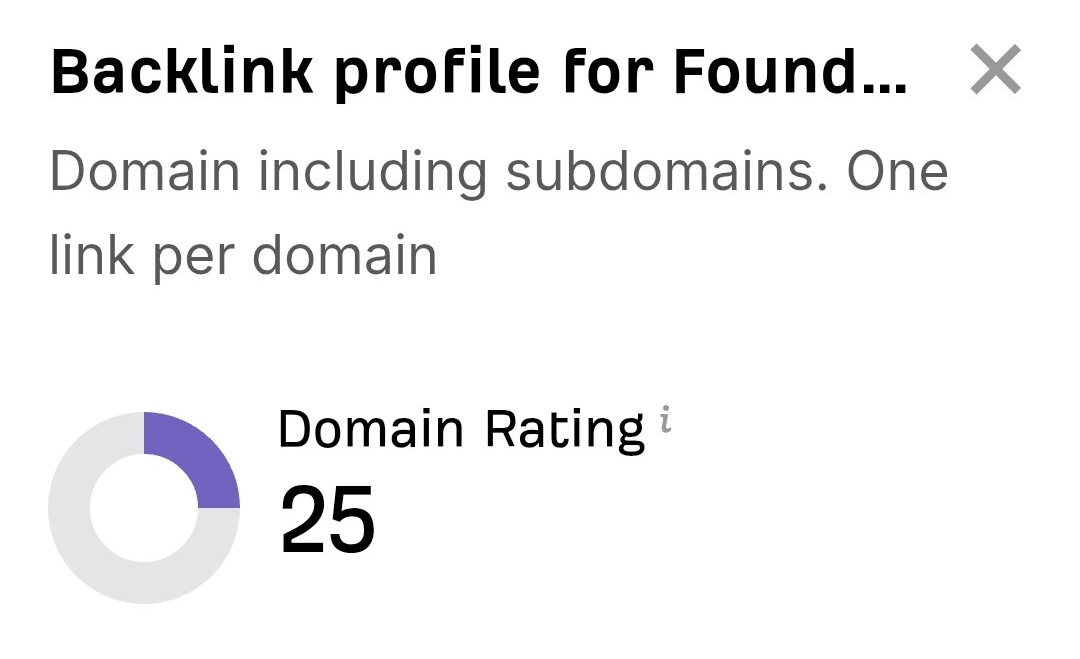 “I just let the Sorank software do its thing, and now my DR is 25 and my page is ranking higher.”
 Lucas FlandrePodcast Host“I specialized in GEO thanks to Sorank. The GEO Leaderboard allows me to show my clients their position vs competitors on ChatGPT. It’s a real commercial differentiator.”
 MélanieSEO Freelance“Great service, works well for our website and helps us understand how to improve it to rank better on Google and elsewhere. Congrats, keep going, I recommend it.”
 Hugo T.E-commerce merchant