Summary
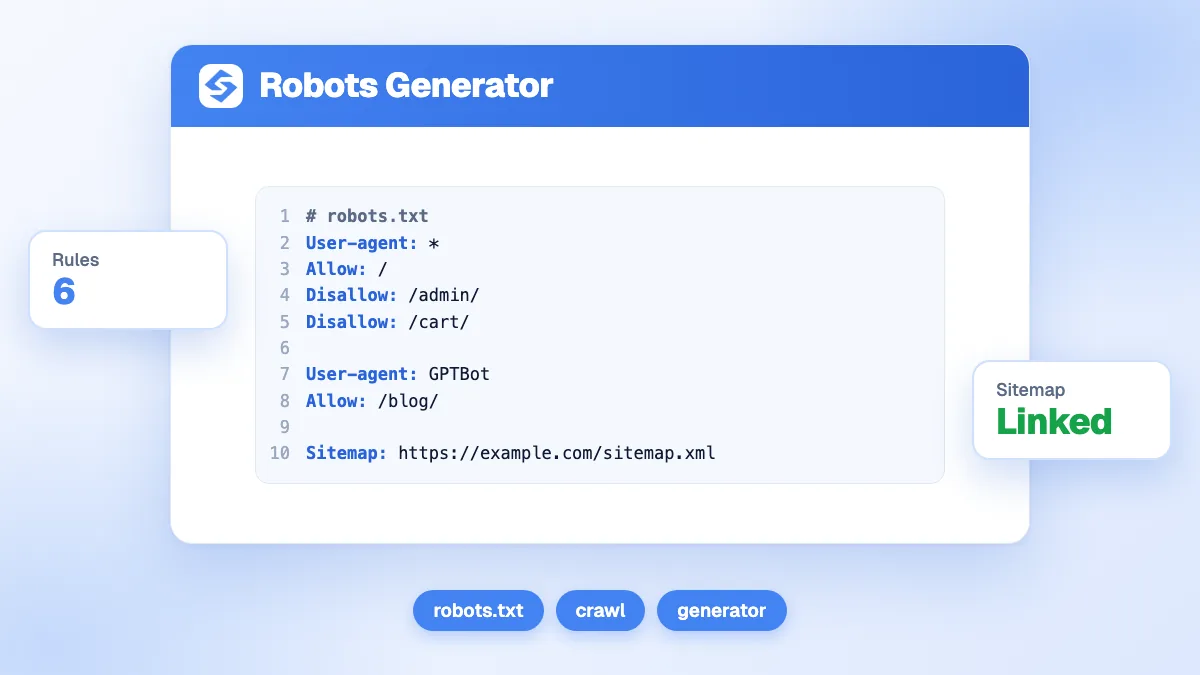
The free robots.txt generator writes the file that tells crawlers which parts of your site they may visit. Pick a mode (allow everything, block everything or custom), list your user-agents and paths, add your sitemap URL, then copy or download the file and upload it to the root of your domain. Remember that robots.txt controls crawling, not indexing: to keep a page out of Google, use noindex instead.
Want to go further? Ask


A robots.txt generator saves you from the small syntax errors that block a whole site by accident. The file follows the Robots Exclusion Protocol, created by Martijn Koster in 1994 and published as an internet standard by the IETF in September 2022 (RFC 9309, Robots Exclusion Protocol). Every serious crawler reads it first, from Googlebot to the bots of ChatGPT, Claude and Perplexity.
What does the robots.txt generator do?
It builds a valid robots.txt as you type, with a live preview on the right, a Copy button and a Download button that saves a file named robots.txt. Nothing is sent to a server: the file is assembled in your browser.
| Setting | What it writes | When to use it |
|---|---|---|
| Allow everything | User-agent: * and Allow: / | Most public sites with nothing to hide from crawlers |
| Block everything | User-agent: * and Disallow: / | Staging or preview sites that must not be crawled |
| Custom | One User-agent line per bot, then your Disallow and Allow paths | Blocking admin areas, internal search or a specific bot |
| Sitemap URL | Sitemap: https://example.com/sitemap.xml | Always, so every crawler finds your sitemap |
| Crawl-delay | Crawl-delay: from 1 to 120 seconds | Only for bots that support it and a server that struggles |
In custom mode, all the user-agents you list share the same rules, which is how the standard defines a group. To give different bots different rules, generate one group at a time and paste them one after the other in the same file.
How do you create a robots.txt file step by step?
- Choose the mode. Start with "Allow everything" unless you have a reason to block something.
- List your user-agents in custom mode, one per line:
*for all crawlers, or names such as Googlebot, Bingbot or GPTBot. - Add the paths to block (Disallow) and the exceptions to keep open (Allow), one per line, each starting with a slash.
- Paste your sitemap URL in full, with https and the domain.
- Copy or download the file and upload it to the root of your host, so that it answers at
https://example.com/robots.txt. - Test it in production with the free robots.txt checker, which reads the live file and shows the status of each AI crawler.
The location is strict. Google only reads a robots.txt at the root of a host, a site can have only one, and the file applies only to the protocol, host and port where it is posted: a subdomain needs its own (Google, create and submit a robots.txt file).
Which robots.txt rules does Google follow?
Google supports four fields: user-agent, allow, disallow and sitemap. Other fields such as crawl-delay are not supported (Google, how Google interprets the robots.txt specification). The same page sets the rules below.
| Rule | How Google applies it |
|---|---|
| Most specific rule wins | When Allow and Disallow both match a URL, the rule with the longest path applies |
| Tie between rules | When two matching rules are equally specific, Google uses the least restrictive one |
| Wildcards | * matches any sequence of characters, $ marks the end of the URL |
| Case | Field names are case-insensitive, but paths are case-sensitive: /Admin/ is not /admin/ |
| File size | Content after the first 500 KiB is ignored |
| Cache | The file is generally cached for up to 24 hours, so a change is not instant |
| Missing file (4xx) | Treated as if there were no restrictions: everything can be crawled |
| Server error (5xx) | Google pauses crawling for 12 hours, then uses the last good copy for up to 30 days |
Here is a typical file for an online shop. It blocks the cart, the checkout and internal search, keeps one public folder open and declares the sitemap.
User-agent: *
Disallow: /cart/
Disallow: /checkout/
Disallow: /search
Allow: /checkout/help/

Sitemap: https://example.com/sitemap.xml
Does Disallow remove a page from Google?
No. Robots.txt is not a mechanism for keeping a web page out of Google. A blocked URL can still be indexed if other sites link to it, and it then appears without a description (Google, introduction to robots.txt). To hide a page, let Google crawl it and add a noindex meta tag or HTTP header. Blocking the page in robots.txt at the same time would stop Google from ever seeing the noindex.
Check the result page by page with the indexability checker, which reads robots.txt, meta robots, X-Robots-Tag and canonical together. For the vocabulary, see our glossary entries on robots.txt and crawling and indexing.
Should you block AI crawlers in robots.txt?
Block the bots that train models if you want to, but keep the bots that power AI search open. The major providers now separate the two, so you no longer have to choose between protecting your content and being cited.
| Provider | Training bot | Search or answer bot | What blocking the search bot costs |
|---|---|---|---|
| OpenAI | GPTBot | OAI-SearchBot | Your pages are not shown in ChatGPT search answers |
| Anthropic | ClaudeBot | Claude-SearchBot | Less visibility in Claude's search results |
| Perplexity | None listed | PerplexityBot | Your pages may not be surfaced or linked in Perplexity results |
| Google-Extended (a token, not a separate bot) | Googlebot | Google-Extended does not affect Google Search or rankings |
Sources: OpenAI crawlers overview, Anthropic crawler policy, Perplexity crawlers and Google common crawlers. To refuse training while staying citable by ChatGPT, a file that contains only these two lines is enough, since every other bot stays allowed by default:
User-agent: GPTBot
Disallow: /
The trend is real: in a single year (2023 to 2024), 28% or more of the most actively maintained sources of the C4 training dataset became fully restricted to AI crawlers (Longpre et al., Consent in Crisis, 2024). Before you follow it, check what blocking costs you in AI answers: Sorank AI mention tracking shows every month whether ChatGPT, Claude and Gemini name your brand.
Which robots.txt mistakes hurt SEO the most?
- Leaving Disallow: / after a launch. Staging files often reach production. One line blocks every crawler from the whole site.
- Blocking CSS and JavaScript. If missing resources make the page harder to understand, Google advises against blocking them.
- Forgetting the trailing slash.
Disallow: /adminalso blocks/administrationand/admin-guide. Write/admin/to block only the folder. - Relying on Crawl-delay for Google. Google ignores it. Anthropic says it supports the extension, so keep it only for bots that read it.
- Using robots.txt as a security tool. The file is public and anyone can read it. Protect private areas with a login, not a Disallow line that points straight at them.
- Forgetting the WordPress exception. The default WordPress file blocks
/wp-admin/but allows/wp-admin/admin-ajax.php, which front-end features use (WordPress developer reference).
How do you check your robots.txt after publishing it?
Use three checks, from the fastest to the most complete.
- Open the URL
https://yourdomain.com/robots.txtin a browser. You should see plain text, not an HTML page or a 404. - Run the robots.txt checker to list rule groups, sitemaps, issues and the status of 14 AI user-agents.
- Open the robots.txt report in Search Console. It shows the files Google found for the top 20 hosts of your site, the last crawl, the warnings, and lets you request a recrawl after an urgent fix (Search Console Help, robots.txt report).
Then complete the setup: generate a clean sitemap with the XML sitemap generator and an llms.txt file with the llms.txt generator, which gives AI assistants a summary of your key pages.
What are the limits of a generated robots.txt?
The generator writes correct syntax, but it cannot know your site. It does not check whether a blocked path holds pages you want ranked, and it writes one group at a time. Bad bots ignore the file entirely: robots.txt is a request, not a wall, so block abusive traffic at the server or firewall level. Finally, the protocol only covers crawling. A page fetched by a user request, such as ChatGPT-User or Perplexity-User, may not follow robots.txt rules, as both providers state in their documentation.
How do you make your site easy to crawl and cite?
A clean robots.txt is the first step. The next ones are publishing pages worth crawling and checking that crawlers actually come back.
- Follow your crawl and your traffic in the GEO and SEO dashboard, which brings Search Console, Analytics and visits from ChatGPT and Perplexity together.
- See which sites AI assistants cite in your market with the GEO leaderboard, and where you rank among them.
- Publish regularly with the blog article generator, so crawlers always find something new.
A two-minute robots.txt protects your crawl budget and your AI visibility at the same time. Generate yours above, test it with the checker, then see the Sorank plans to keep your site crawlable and cited on autopilot.