
Preferences
Privacy is important to us, so you have the option of disabling certain types of storage that may not be necessary for the basic functioning of the website. Blocking categories may impact your experience on the website. More information

Privacy is important to us, so you have the option of disabling certain types of storage that may not be necessary for the basic functioning of the website. Blocking categories may impact your experience on the website. More information

What the Search Console status Duplicate without user-selected canonical means, when it is normal, how to diagnose it with URL Inspection and how to fix it.
Tools


In short
"Duplicate without user-selected canonical" is a status in the Page indexing report of Google Search Console. It means Google found a URL that duplicates another page, the URL does not declare a preferred version, so Google picked another URL as the canonical and left this one out of search results. It is often normal (parameter URLs, HTTP or www variants). It becomes a problem when Google picks the wrong URL or groups pages you want ranked as duplicates: inspect the URL, then fix it with a 301 redirect, a rel="canonical" tag or more distinct content.
Want to go further? Ask
Quick quiz
Which way of finding customers online fits you best?
4 quick questions to choose your main channel.
Our advice for you
Sorank is the right solution for you
Your customers search before they buy: articles that answer their questions bring them for months. Sorank writes and publishes them, and tracks what ChatGPT says about you.
Sorank matches your answers
Test it for 3 days on your own site, or start with a free audit to see where you stand.
3 days free, then stop whenever you want. 90-day money-back guarantee.
Duplicate without user-selected canonical is one of the reasons listed under "Why pages aren't indexed" in Search Console. Google's Page indexing report documentation describes it in one line: "This page is a duplicate of another page, although it doesn't indicate a preferred canonical page." This guide explains what that means, how to tell a harmless case from a real problem, how to diagnose it with the URL Inspection tool and which fix to apply in each situation.
When several URLs show the same or nearly the same content, Google groups them and indexes only one: the canonical. Google calls this process canonicalization, "the process of selecting the representative" URL of a piece of content, in its Search Central guide to canonicalization.
The status tells you three things about the URL listed in the report:
The excluded URL is not penalized. Its content is still eligible to appear in Google, through the canonical URL that Google kept. Google's help center states that this "is not an error, but is working as intended, because Google does not serve duplicate pages."
Search Console has three statuses linked to canonicals, and they are easy to mix up:
| Status | What happened | Who chose the canonical | Action |
|---|---|---|---|
| Duplicate without user-selected canonical | Duplicate URL with no declared canonical | Check that Google's choice is the right URL | |
| Alternate page with proper canonical tag | The page points to an indexed canonical, as intended | You (and Google agreed) | None, according to Google |
| Duplicate, Google chose different canonical than user | You declared a canonical, Google picked another URL | Google, against your choice | Investigate: your signals contradict each other |
Most sites have some URLs in this status, and a small, stable number is no cause for concern. Google's guide confirms that "some duplicate content on a site is normal and it's not a violation of Google's spam policies." What matters is which URLs are listed and which canonical Google picked.
| Normal: leave it | Problem: act |
|---|---|
| URLs with tracking parameters (?utm_source=, ?ref=, session IDs) | Google picked a parameter URL, the HTTP version or an old URL as canonical |
| The HTTP or non-www version of a page served correctly over HTTPS | Product, service or location pages you want ranked are grouped as duplicates |
| Sorting and filtering URLs of a category page | The number of affected URLs jumps after a migration, a redesign or a CMS change |
| Print versions or near-identical archive pages | A staging or demo site is crawlable and duplicates your live pages |
The rule of thumb: if the Google-selected canonical is the URL you would have chosen yourself, there is nothing to fix. If it is not, or if a page you need in search results is excluded as a duplicate, act.
Google's guide lists the usual sources of duplicate content: region variants, device variants, protocol variants, site functions such as "the results of sorting and filtering functions of a category page", and accidental variants such as a demo site left open to crawlers. On real sites, the most frequent cases are:
In Google Search Console, go to Indexing, then Pages, scroll to "Why pages aren't indexed" and click the status. Export the example URLs. Google notes that this list "is limited to 1,000 items" and is not guaranteed to show every affected URL.
Sort the export and look for what the URLs share: a parameter, a folder, a protocol, a trailing slash. Ten thousand affected URLs often come from two or three patterns, and each pattern gets one fix.
Paste a URL into the search bar at the top of Search Console. In the Page indexing section of the URL Inspection tool, read two fields:
Open the inspected URL and the Google-selected canonical side by side. Ask two questions: is the content the same, and is Google's choice the URL you want users to land on? Then inspect the Google-selected canonical itself to confirm it is indexed.
Watch out
The live test cannot answer the canonical question. Google states that you can determine the canonical "only in the indexed data; the live test cannot predict whether or not the tested version will be considered canonical." Read the indexed result, not the live test.
To check what your pages declare before Google recrawls them, run them through our free canonical tag checker: it shows the canonical in the HTML of any URL in a few seconds.
The fix depends on what you want for the duplicate URL. Google's guide to consolidating duplicate URLs ranks the signals by strength: redirects and rel="canonical" are strong signals, sitemap inclusion is a weak one.
| Situation | Fix | Signal strength |
|---|---|---|
| The duplicate URL has no reason to exist (HTTP, non-www, old URL) | 301 redirect to the preferred URL | Strong |
| The duplicate must stay reachable (parameters, filters, variants) | rel="canonical" pointing to the preferred URL | Strong |
| The page deserves to rank on its own | Make the content substantially different, plus a self-referencing canonical | Depends on the content |
| Supporting the choice | Internal links and the XML sitemap pointing only to the canonical | Weak, but consistent |
For protocol, host and trailing slash variants, a site-wide 301 redirect is the cleanest fix: users and crawlers always land on one URL. Our guide to SEO redirects explains how to set them up without chains.
Add a link element in the head of the duplicate: <link rel="canonical" href="https://www.example.com/preferred-page/">. Use absolute URLs. Google also recommends a self-referencing canonical on the preferred page itself, so every indexable page states its own URL.
If Google groups pages you want indexed separately, the tag alone will not help. Google's help center says that if a page is not a duplicate of the chosen canonical, "you should ensure that the content differs substantially between the two pages." Add specific text, data, photos, prices or local details to each page.
Point internal links to the canonical URL, list only canonical URLs in your XML sitemap and check it with a sitemap checker. Mixed signals (a sitemap listing one URL, links pointing to another) are what lead Google to choose differently from you.
Note
Google advises against three common shortcuts for canonicalization: blocking duplicates in robots.txt, using noindex to pick a canonical within a site, and using the URL removal tool. Each one hides content instead of consolidating it.
Nothing changes until Googlebot recrawls the affected URLs. After the fix, you can start a validation from the status page; Google says validation "typically takes up to about two weeks, but in some cases can take much longer." Validation is optional: the report updates on its own as pages are recrawled. For a few important URLs, request indexing in the URL Inspection tool. For large sites, the URL Inspection API lets you check canonicals in bulk, within a quota of 2,000 queries per day per site according to the Search Console API usage limits. Our guide to Google indexing covers the rest of the indexing pipeline.
Duplicates split signals. Links, internal links and engagement spread across several URLs instead of supporting one, and the URL shown in results may be the one you like least (a parameter URL, a filtered page). On large sites, crawling duplicates also takes time Googlebot could spend on new pages.
AI assistants add a second reason. ChatGPT, Perplexity and Gemini answer many questions by retrieving pages from search indexes, then citing the URL they found. When your content exists at one clean canonical URL, that is the address that gets retrieved, cited and clicked. When it exists at five, signals are diluted and the cited link may point to a variant you would rather not show.
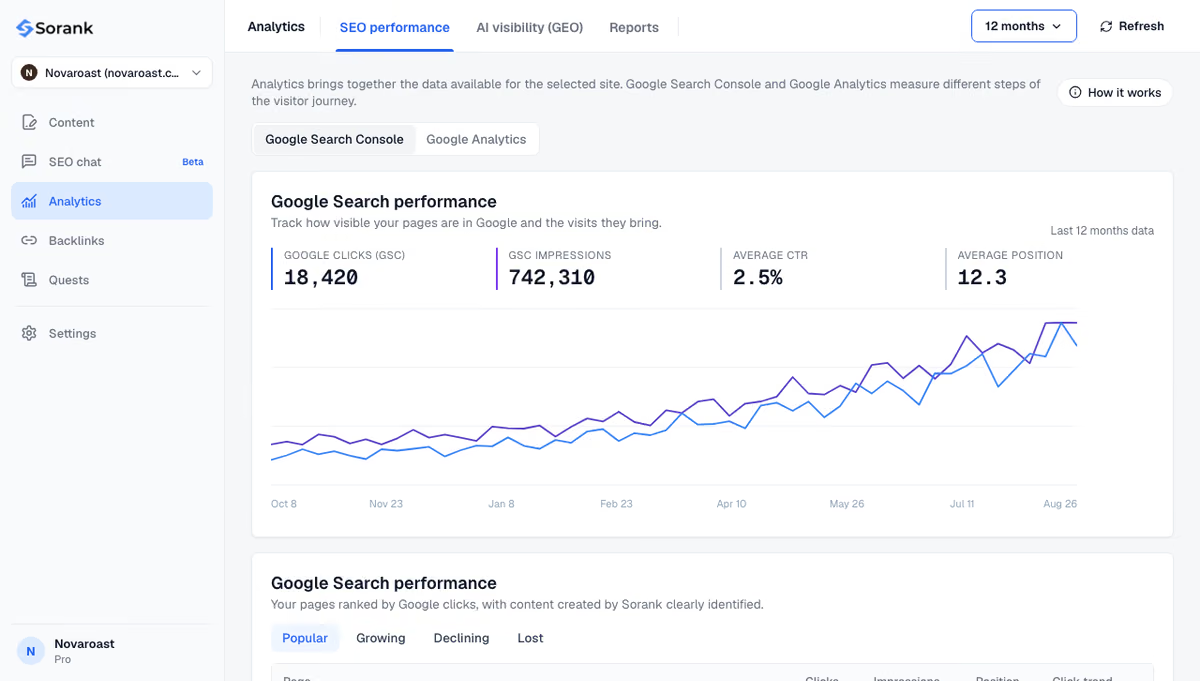
Sorank is our product: an autopilot SEO and GEO software. Its GEO and SEO dashboard shows clicks, impressions and positions from Search Console, so you can see whether canonical fixes bring traffic back to the right pages, and AI mention tracking checks every week whether ChatGPT, Claude and Gemini cite your brand.
The short version: check the Google-selected canonical, redirect what should not exist, declare a canonical on what you keep, and make pages that deserve to rank truly different. To grow the number of pages that do get indexed and cited, see Sorank's plans, from $49 per month with a 3-day free trial.

Not by itself. Google indexes the canonical URL it selected and shows that one in search results, so the content stays eligible to rank. It hurts only when Google picks the wrong URL as canonical, or when pages you want ranked separately are treated as duplicates of another page.
No. Parameter URLs, HTTP or non-www variants and sorting pages are expected in this status and need no action if Google picked the right canonical. Focus on URLs where the Google-selected canonical is wrong, on pages you need in search results, and on sudden increases after a site change.
Google advises against using noindex to choose a canonical within a site, because noindex removes the page from search entirely instead of consolidating its signals into the preferred URL. Use a 301 redirect when the duplicate should not exist, and a rel canonical tag when it must stay reachable for users.
 AI Content Brief Generator
 FAQ Schema Generator
 AI Blog Post Ideas Generator
 Structured Data Validator
 Alt Text Checker
 Internal Link Analyzer
 Backlink Challenge
 AI Meta Description Generator
 AI Blog Title Generator
 Google Indexability Checker
 AI Blog Outline Generator
 UTM Link Builder
 Keyword Clustering Tool
 Canonical Tag Checker
 XML Sitemap Generator
 Broken Link Checker
 AI SEO Title Generator
 Headline Analyzer
 SERP Preview Tool
 Redirect Checker
 Hreflang Tag Generator
 Heading Structure Analyzer
 HTTP Headers Checker
 Favicon Extractor
 SERP CTR Calculator
 SEO vs Paid Search Savings Calculator
 SEO Share of Voice Calculator
 SEO ROI Calculator
 SEO Traffic and Revenue Forecast Calculator
 SEO Budget Calculator
 SEO Break-Even Calculator
 SaaS SEO ROI Calculator
 ROAS Calculator
 Reading Time Calculator
 Ranking Gain Simulator
 Organic Traffic Value Calculator
 Organic Traffic Estimator
 LTV to CAC Ratio Calculator
 Local SEO ROI Calculator
 Link Building Cost Calculator
 Keyword Value Calculator
 Keyword Opportunity Score Calculator
 Keyword Density Calculator
 GEO ROI Calculator
 GEO Content Investment Calculator
 Ecommerce SEO ROI Calculator
 Customer Lifetime Value Calculator
 Customer Acquisition Cost Calculator
 CTR Calculator
 Cost Per Article Calculator
 Conversion Rate Calculator
 Content Marketing ROI Calculator
 ChatGPT Referral Traffic Estimator
 Bounce Rate Calculator
 Backlink ROI Calculator
 AI Visibility Score Calculator
 AI Traffic Value Calculator
 AI Share of Voice Calculator
 Cost of AI Invisibility Calculator
 AI Citation Rate Calculator
 llms.txt Validator
 AI Overview Checker
 Robots.txt Checker
 AI SEO Audit
 LLM Readability Checker
 SearchGPT Readiness Checker
 Structured Data LLM Audit
 Website Crawlability AI Audit
 Why ChatGPT Is Not Recommending My Website
 Gemini Ranking Tool
 Perplexity Ranking Checker
 LLM Citation Checker
 Answer Engine Optimization Audit
 GEO Audit
 AI Search Visibility Test
 ChatGPT Visibility Checker
 llms.txt Generator
 URL Extractor
 Webpage to Markdown
 Sitemap Checker
 SERP Volatility Sensor
 Page Size Checker
 Word Counter
 Slug Generator
 Schema Generator
 Robots Generator
 OG Preview
 Meta Tags Generator
 Image Compressor
 Favicon Generator
 On-Page SEO Audit
 Backlink Analysis Tool
 Keyword Research Tool
 Domain Authority Checker
THEY TRIED SORANK BEFORE YOU
 “I tested Sorank on a real client site and it's insane. It does everything an agency would bill you $1500 a month for. It's going into production on that client now.”

 Guillaume Guersanguersanguillaume.com“We are an Ads agency and we wanted to get our SEO back on track once and for all. Sorank gave us a clear view of our site, helped us prioritize optimizations, and properly structure our content. The tool is easy to use, well designed for a team, and very practical for centralizing tracking without having to juggle multiple platforms. A very solid foundation to start fresh with our SEO.”
 Gaspard MadouiAds Agency
 “I just let the Sorank software do its thing, and now my DR is 25 and my page is ranking higher.”
 Lucas Flandrefoundertrace.fr“I specialized in GEO thanks to Sorank. The GEO Leaderboard allows me to show my clients their position vs competitors on ChatGPT. It’s a real commercial differentiator.”
 MélanieSEO Freelance“Great service, works well for our website and helps us understand how to improve it to rank better on Google and elsewhere. Congrats, keep going, I recommend it.”
 Hugo T.E-commerce merchant
























